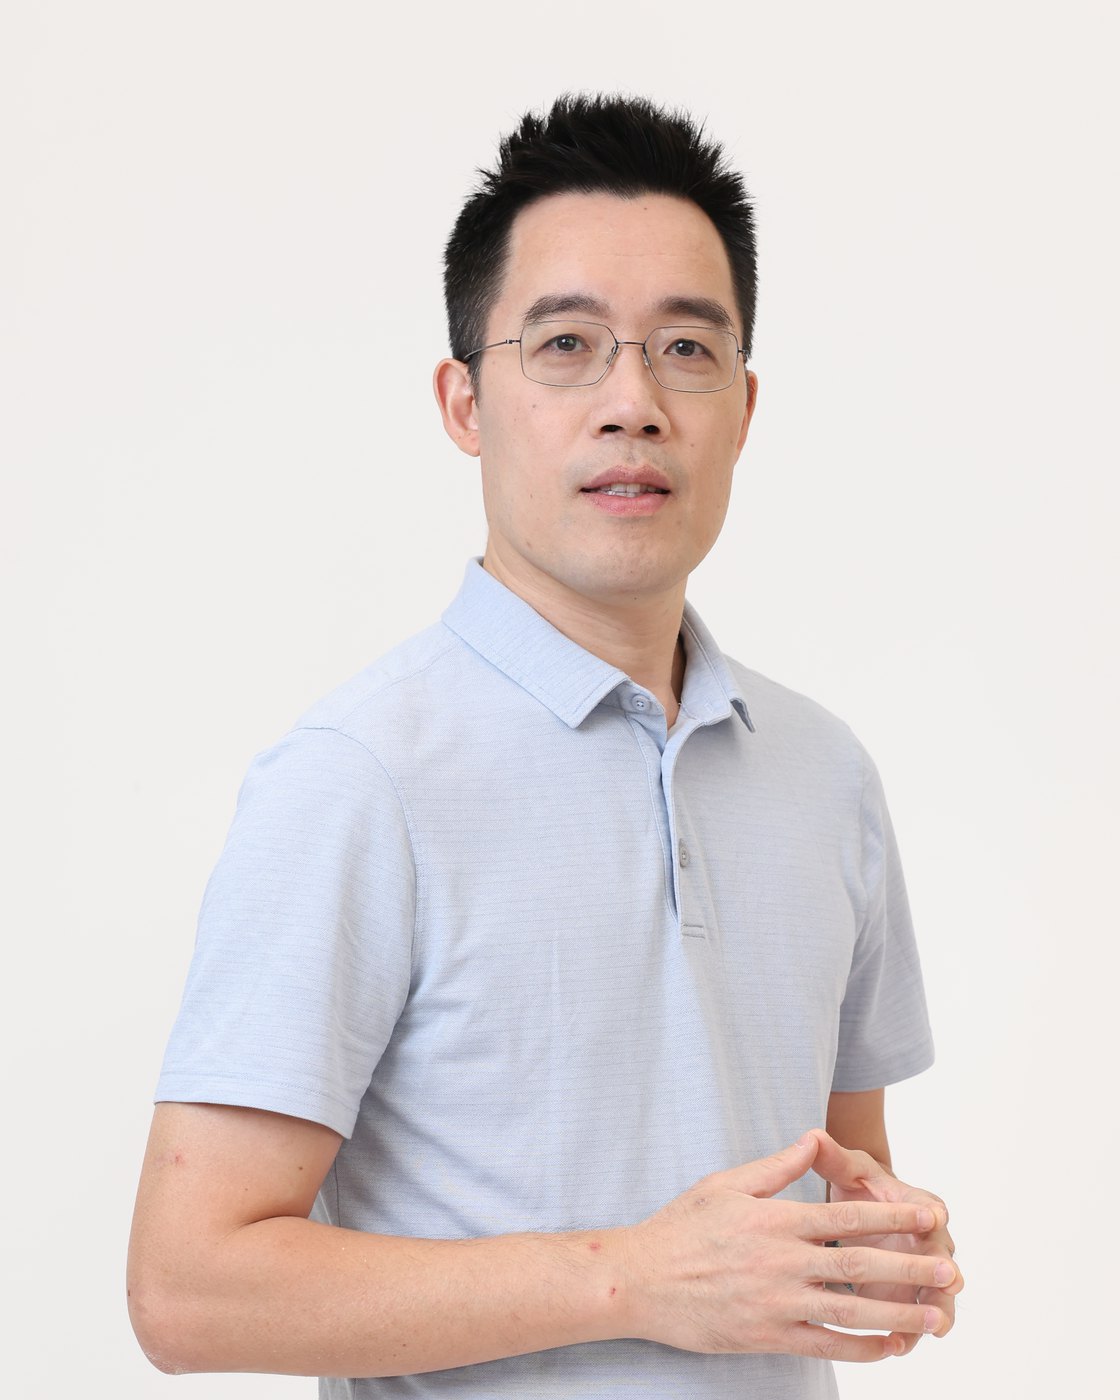
Associate Professor · CUHK-Shenzhen副教授 · 香港中文大学(深圳)
Zhizheng Wu武执政
I work on speech and audio AI, and build open-source tools, datasets, and community challenges that others can build on. 研究语音与音频人工智能,长期投入开源:做工具、建数据集、办评测,让更多人能在此基础上继续往前走。
Media媒体报道
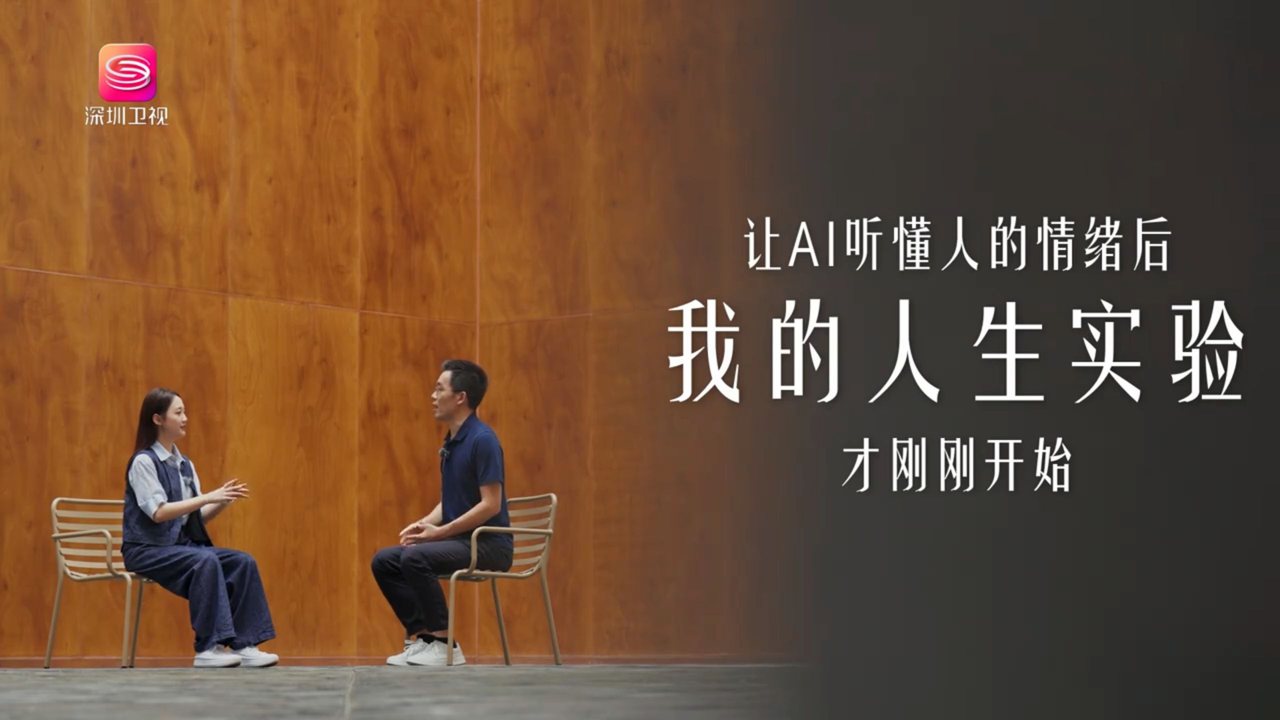 Interview with Shenzhen Satellite TV深圳卫视专访
Research研究方向
-
Speech generation语音生成
Zero-shot text-to-speech, voice imitation, and singing voice generation that can be controlled and scaled.零样本语音合成、声音克隆与歌声生成,追求可控、好用、能规模化。
MaskGCT · Metis · Vevo and Vevo2 · FlexiVoice · NaturalSpeech 3 · FlexiVoice · SpeechJudge
-
Speech language models语音大模型
How well speech language models reason and understand, and how to judge generated speech the way people do.让语音大模型真正听得懂、会推理,并探索如何像人一样评判合成语音的好坏。
FlexiSLM · SD-Eval · TARS · AURAL · ConvexLLM · EvoAudio · Jarvis
-
Speech tokenizers and neural codecs语音表征与神经编解码
Compact, low-frame-rate representations of speech that language models can read and write.把语音压成紧凑、低帧率的离散表示,让大模型读得懂、写得出。
FlexiCodec · TaDiCodec · DualCodec · TASLA
-
Trustworthy audio AI音频安全与可信 AI
Spoofing and deepfake detection, adversarial attacks on speaker verification, spoken misinformation, and privacy.伪造语音检测、声纹系统的对抗攻防、语音虚假信息识别与隐私保护。
ASVspoof · AdvSV · SpMis · VoxPrivacy · VoxSafeBench
Representative papers代表论文
-
FlexiSLM: A Spoken Language Model with Dynamic and Controllable Frame Rates
Conference会议 EMNLP 2026
-
Vevo2: A Unified and Controllable Framework for Speech and Singing Voice Generation
Journal期刊 IEEE/ACM Transactions on Audio, Speech, and Language Processing, 2026
-
MaskGCT: Zero-Shot Text-to-Speech with Masked Generative Codec Transformer
Conference会议 ICLR 2025
-
Emilia: An Extensive, Multilingual, and Diverse Speech Dataset for Large-Scale Speech Generation
Conference会议 IEEE Spoken Language Technology Workshop (SLT) 2024
-
Spoofing and Countermeasures for Speaker Verification: A Survey
Journal期刊 Speech Communication, 66, pp. 130–153, 2015
About个人简介
Zhizheng Wu is an Associate Professor at The Chinese University of Hong Kong, Shenzhen. He received his Ph.D. from Nanyang Technological University and has held positions at Meta (formerly Facebook), Apple, the University of Edinburgh, and Microsoft Research Asia.
Professor Wu has initiated several open-source projects, including Merlin, Amphion, and Emilia. He also initiated and organized the first ASVspoof Challenge and the first Voice Conversion Challenge, and served as an organizer of the Blizzard Challenge 2019.
He currently serves on the editorial boards of IEEE/ACM Transactions on Audio, Speech, and Language Processing and IEEE Signal Processing Letters. He was the General Chair of the IEEE Spoken Language Technology Workshop 2024 and will serve as the General Chair of the IEEE Conference on Artificial Intelligence 2027.
武执政,香港中文大学(深圳)副教授,博士毕业于新加坡南洋理工大学。加入港中大(深圳)之前,曾在 Meta、苹果、爱丁堡大学和微软亚洲研究院从事研究与研发工作。
他是 Merlin、Amphion、Emilia 等开源项目的发起人,也是首届 ASVspoof 声纹防伪挑战赛和首届语音转换挑战赛(Voice Conversion Challenge)的发起人与组织者,并参与组织了 Blizzard Challenge 2019。
目前担任 IEEE/ACM Transactions on Audio, Speech, and Language Processing 和 IEEE Signal Processing Letters 编委;曾任 IEEE SLT 2024 大会主席,并将出任 IEEE CAI 2027 大会主席。
Open source开源项目
Challenges国际评测与挑战赛
- ASVspoof Initiated and organized the first challenge on speaker verification spoofing and countermeasures.发起并组织首届比赛,聚焦声纹识别的伪造攻击与防御。
- Voice Conversion Challenge语音转换挑战赛(Voice Conversion Challenge) Initiated and organized the first edition.发起并组织首届比赛。
- Blizzard Challenge 2019 Organizer.担任组织者。
Service学术服务
-
General Chair大会主席
IEEE Conference on Artificial Intelligence 2027 (upcoming)IEEE Conference on Artificial Intelligence 2027(筹办中)
IEEE Spoken Language Technology Workshop 2024 -
Editorial board编委
IEEE/ACM Transactions on Audio, Speech, and Language Processing
IEEE Signal Processing Letters
Contact联系方式
Writing about one of these? The buttons start an email with the subject filled in.来信请按需选择,点一下就能发邮件,主题已经帮你填好。
Room 715, Teaching Complex C
The Chinese University of Hong Kong, Shenzhen
Shenzhen, China广东省深圳市龙岗区龙翔大道 2001 号
香港中文大学(深圳)教学楼 C 栋 715 室